What it looks like
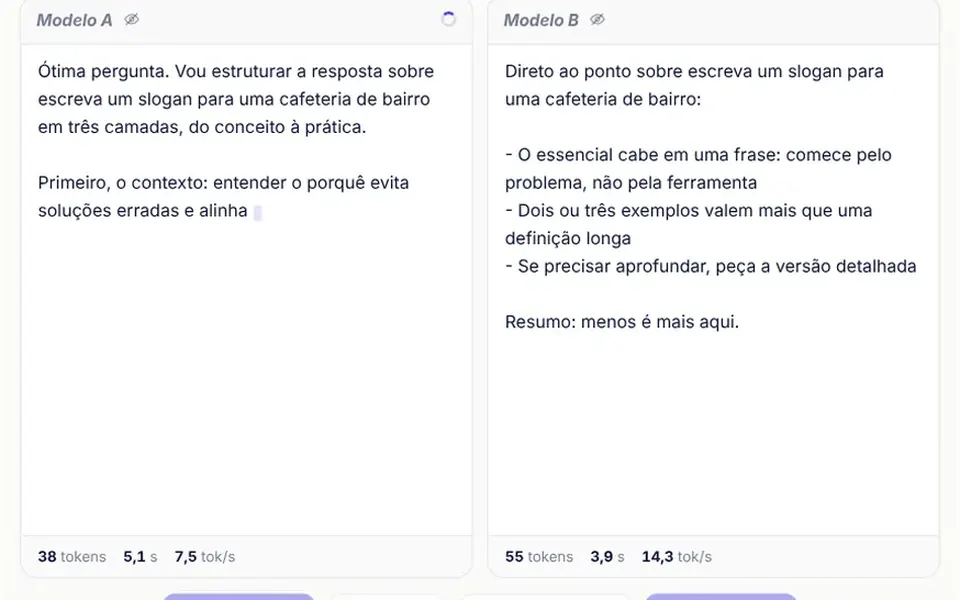
It resembles a blind taste test with the labels hidden. On a light card, the top shows the arena title and the round number, with the question below in bold, next to a speech bubble icon. Two columns, model A and model B, receive text bit by bit, each at its own pace, with a spinning indicator and a cursor at the end of the line. Each column footer shows tokens, seconds and tokens per second rising live. When both finish, the vote buttons light up; after the vote, names appear, the winner gets an accent border and the other fades. At the bottom, the scoreboard adds up the wins.
You may be looking for this if you asked for something like
- compare answers from two AI models side by side
- a blind test so my team can pick the AI that answers better
- vote for the stronger answer without knowing which model wrote it
- a prompt evaluation screen with a win scoreboard
- show each model's speed in tokens per second
- a chatbot arena where AIs compete, for my team
- choose between two models before shipping to production
Also known as
- model arena
- LLM comparison
- side-by-side eval
- blind A/B test
- model evaluation
- prompt comparison
When to use
- Evaluating models and prompts side by side before choosing what ships
- Internal rounds where the team votes blind, free from brand bias
- Client demos that compare two AI providers
- Evaluation tools that record votes and metrics per round
When to avoid
- Exact cost measurement, since token counts are an in-house estimate, not the model tokenizer
- Evaluations that must keep history without integration, because the scoreboard lives only in page memory
- English interfaces as is, since buttons and labels are in Portuguese
How to ask your AI
Create a blind arena to compare two AI models in my internal dashboard: the same question answered side by side with streaming, names hidden until the vote, A, B, tie and both bad buttons, token and time metrics, stacked columns on phones and a scoreboard saved to my API.
With THM Componentes, you paste the full prompt from the catalog, which already includes this component's source code, and the AI reproduces this exact effect instead of improvising.
Questions about Degustação
How do I connect Degustação to my models?
Pass at least two models in the sources prop, each with a name and a respond function that takes the prompt and returns the answer in chunks as an async stream. Degustação picks the pair and the question for each round from a seed and accepts your own questions in the questions prop.
Is Degustação's scoreboard saved?
Not on its own. Degustação keeps the scoreboard and history only while the page is open. To record results, use the vote event, which carries the round, question, both names and the vote, and store it in your API; the getBoard method reads the current scoreboard.
Are Degustação's token metrics exact?
They are an estimate. Degustação counts words, numbers and symbols in the answer to get tokens and measures elapsed time in the browser, computing tokens per second live. It is useful for comparing pace and length between models; for cost, use the counts each model API returns.